Jun 2026 — Present
Data Engineer (Data and AI Platforms)
 Applied Materials
Building data foundations for MLOps and AI, connecting reliable pipelines with platforms that support machine learning and AI applications.
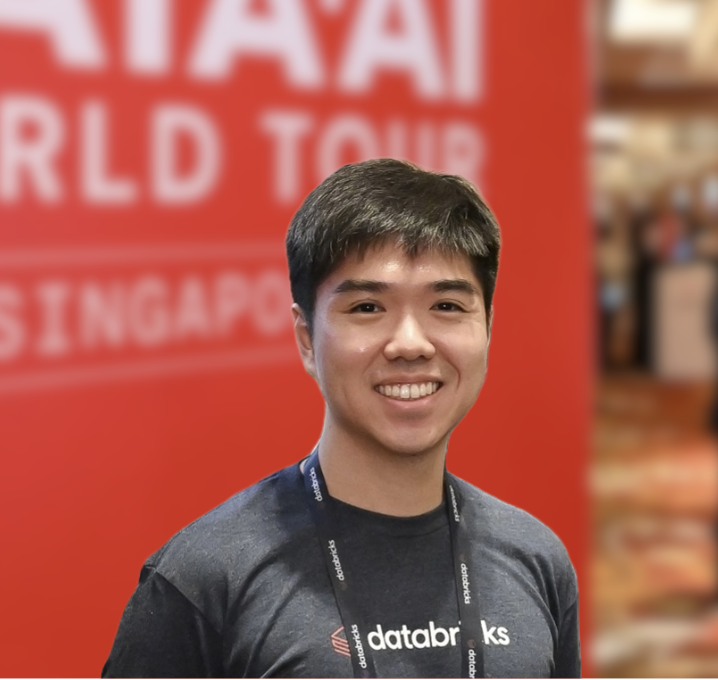
I’m a data engineer with 7 years of experience across technology and financial services, building reliable data platforms that power analytics, machine learning and AI.
Today at Applied Materials, I build data foundations for MLOps and AI in a complex global supply chain environment.
Previously, I worked across data engineering, analytics and technical advisory, with a focus on turning data into measurable business outcomes:
I enjoy working at the intersection of data engineering, AI and business problems, especially where better data can make complex systems easier to understand and operate.
THE JOURNEY
Technical advisory, data platforms and applied analytics.
Jun 2026 — Present
Applied Materials
Building data foundations for MLOps and AI, connecting reliable pipelines with platforms that support machine learning and AI applications.
Jul 2025 — Jan 2026
 Databricks
Technical advisor in pre-sales, helping customers design and adopt data and AI solutions on Databricks.
Aug 2022 — Jun 2025
 JLL· Supporting
 Google REWS
Vendor Data Engineer through JLL, building data foundations for Google Real Estate & Workplace Services (REWS).
Oct 2019 — Aug 2022
 HSBC
Combined data engineering, analytics and predictive modeling across two roles.
THE TOOLBOX
Data engineering depth. Practical AI. Business context.
The tools I use to query, transform and work with data.
Cloud warehouses and distributed data platforms.
Reliable pipelines, well-defined models and efficient workloads.
From predictive models to practical AI applications.
Tested code, integration and repeatable delivery.
CONTINUOUS LEARNING
Credentials in cloud architecture, data engineering and machine learning.
Amazon Web Services (AWS)
Issued Dec 2025 · Expires Dec 2028
Verify credential (opens in a new tab)Databricks
Issued Aug 2025 · Expires Aug 2027
Credential ID: 159535646
Verify credential (opens in a new tab)Databricks
Issued Jul 2025 · Expires Jul 2027
Credential ID: 156084207
Verify credential (opens in a new tab)SELECTED WORK
Applied AI and reliable data foundations.
Turning unstructured emails into validated data, ready to query.
Emails contain useful business context, but free-form text is difficult to classify, search and use in downstream workflows.
Connects LLM extraction to warehouse storage and an API with intent filtering, making email content available as structured records.
Prompt comparison is qualitative; a scored evaluation dataset remains future work.
From historical housing transactions to traceable, quality-checked datasets.
Historical resale files vary in schema and require explicit rules for missing fields, duplicates and unusual prices before they can support consistent analysis.
Produces cleaned, transformed and SHA-256-hashed outputs for 2012–2016 transactions, with separate rejection and anomaly reports.
Compact identifiers can collapse distinct transactions. Collision reports make that trade-off visible; the cleaned dataset remains available before identifier-level deduplication.